Component-based algorithms
- Author:
Antonio J. Nebro
- Version:
1.2
- Date:
2026-6-12
The design and architecture of the metaheuristics included in jMetal is probably the feature that has evolved
the most since the start of the project in 2006. In first versions, the implementation of a metaheuristic required
to implement an Algorithmn abstract class, which had an execute() abstract method that had to be implemented by any
algorithm. As a consequence, developers were free to write the code of an algorithm without any constraint,
resulting in many cases in codes that were difficult to extend and to reuse. To give an example, the
execute() code of our implementation of NSGA-II was about 130 lines long, and the development of a
steady-state version of NSGA-II was made by copying all of that code and modifying a few lines from de original
code. This architecture was described in the paper jMetal: A Java framework for multi-objective
optimization, published in Advanced in Engineering Software
in 2011, and it was used until jMetal version 4.5.
We took the decision of redesigning jMetal from scratch in 2014, leading to jMetal 5.0 a year later. The main features of that version were presented in the EvoSoft of the GECCO conference in 2015 (Redesigning the jMetal Multi-Objective Optimization Framework), including the inclusion of algorithm templates for metaheuristics such as evolutionary algorithms and particle swarm optimization techniques. In this way, code reuse was significantly improved but at the cost of having to take into account the use of templates, which has proved cumbersome for some researchers, and the consequence is that there are still people using jMetal 4.5.
Now, in the current release of jMetal (version 7.11), we propose a new architecture for the design and implementation of metaheuristics. The main reason has to do with the fact that we are currently interested in using jMetal for the auto-configuration and auto-design of algorithms, and the current architecture has limitations for this, as discussed in the paper Automatic Configuration of NSGA-II with jMetal and irace (GECCO Companion 2019). The idea is to use a component-based approach, were algorithmic templates are again used but the steps of the algorithms are implemented as objects instead of methods so, instead of using inheritance, implementing a given algorithm requires to add the proper components to the template. The resulting architecture allow metaheuristics to be highly configurable without the need of defining sub-clases. Furthermore, the templates are observable entities, according to the Observer pattern, so observers entities can register into them and be notified when the state of the algorithm changes (e.g., a real chart observer can receive the population after each algorithm iteration to plot it).
Contrarily to the approach adopted in jMetal 5.0, in jMetal 7.11 the new architecture is not going
to replace the former one. There are some reasons for taking this decision, starting with
the aforementioned comment about jMetal users who are comfortable with the current implementation
and are probably not interested
in learning another way of developing or using the algorithms. Another reason is that algorithms
having tightly related components can be difficult to be implemented with the component-
based architecture; this way, while NSGA-II adapts very well to the architecture, to implement MOEA/D
we had to design some complex components. As a consequence, all the component-related stuff is
located in a new Maven sub-project called jmetal-component.
The structure of jmetal-component is depicted in this figure:
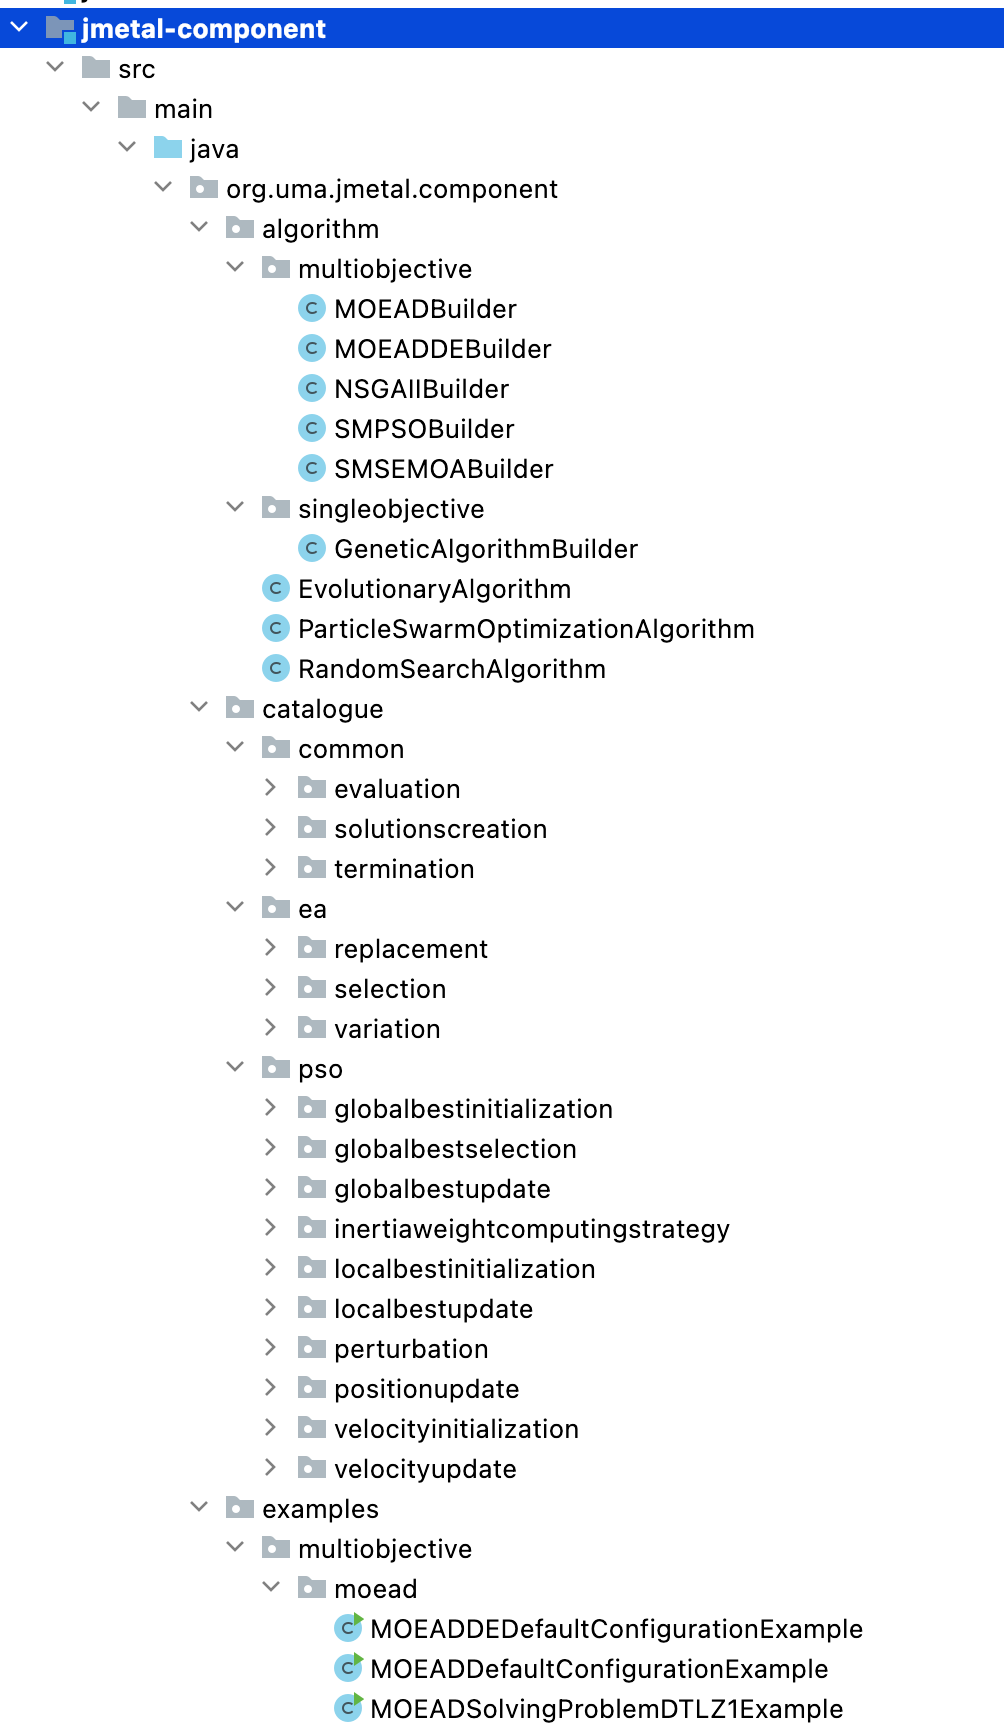
The main packages of the sub-project are the following:
algorithm: Contains the algorithmic templates (such asEvolutionaryAlgorithmandParticleSwarmOptimization) as well as builder classes to instantiate single- and multi-objective metaheuristics from them.catalogue: The components are included in a catalogue that is structured into three sub-packages:common: Components that can be part of any algorithm.ea: Specific components for evolutionary algorithms.pso: Specific components of particle swarm optimization techniques.
examples: Contains plenty of examples of how to use the templates to configure, create, and execute algorithms.
The EvolutionaryComputation template
The component-based template for evolutionary algorithms is implemented in the
org.uma.jmetal.component.algorithm.EvolutionaryComputation class. The following code snippet shows
its state variables, which include the evolutionary components (create the initial population, evaluation, selection, variation, replacement, and termination) and the attributes map (containing
the information that will be notified to observers):
package org.uma.jmetal.component.algorithm;

public class EvolutionaryAlgorithm<S extends Solution<?>>
  implements Algorithm<List<S>>, ObservableEntity<Map<String, Object>> {

  private List<S> population;

  private Evaluation<S> evaluation;
  private SolutionsCreation<S> createInitialPopulation;
  private Termination termination;
  private Selection<S> selection;
  private Variation<S> variation;
  private Replacement<S> replacement;

  private final Map<String, Object> attributes;

  private long initTime;
  private long totalComputingTime;
  private int evaluations;

  private final Observable<Map<String, Object>> observable;

...
}
The run() method of the class carries out the steps of a generic evolutionary algorithm:
public void run() {
  initTime = System.currentTimeMillis();

  population = createInitialPopulation.create();
  population = evaluation.evaluate(population);
  initProgress();
  while (!termination.isMet(attributes)) {
    List<S> matingPopulation = selection.select(population);
    List<S> offspringPopulation = variation.variate(population, matingPopulation);
    offspringPopulation = evaluation.evaluate(offspringPopulation);

    population = replacement.replace(population, offspringPopulation);
    updateProgress();
  }

  totalComputingTime = System.currentTimeMillis() - initTime;
}
The state of the algorithm is updated with methods initProgress() and updateProgress():
protected void initProgress() {
  evaluations = population.size();

  attributes.put("EVALUATIONS", evaluations);
  attributes.put("POPULATION", population);
  attributes.put("COMPUTING_TIME", currentComputingTime());
}

protected void updateProgress() {
  evaluations += variation.offspringPopulationSize();

  attributes.put("EVALUATIONS", evaluations);
  attributes.put("POPULATION", population);
  attributes.put("COMPUTING_TIME", currentComputingTime());

  observable.setChanged();
  observable.notifyObservers(attributes);

  totalComputingTime = currentComputingTime();
}
As it can be observed, the initProgress() method initializes the evaluation counter and sets
three attributes: evaluations, population, and computing time. The updateProgress() method
is invoked at the end of each iteration and, besides updating the same elements as initProgress(), notifies observers the new attribute values.
Configuring a particular evolutionary algorithm with the EvolutionaryAlgorithm class merely requires to instantiate it the proper components. To facilitate this task, we provide builder classes that allows to get algorithms configured with default settings and facilitates to indicate particular parameter values. Let us consider the NSGA-II algorithm; the constructor of the NSGAIIBuilder
class is the following one:
public NSGAIIBuilder(Problem<S> problem, int populationSize, int offspringPopulationSize,
    CrossoverOperator<S> crossover, MutationOperator<S> mutation) {
  name = "NSGAII";

  densityEstimator = new CrowdingDistanceDensityEstimator<>();
  ranking = new FastNonDominatedSortRanking<>();

  this.createInitialPopulation = new RandomSolutionsCreation<>(problem, populationSize);

  this.replacement =
      new RankingAndDensityEstimatorReplacement<>(
          ranking, densityEstimator, RankingAndDensityEstimatorReplacement.RemovalPolicy.ONE_SHOT);

  this.variation =
      new CrossoverAndMutationVariation<>(
          offspringPopulationSize, crossover, mutation);

  int tournamentSize = 2;
  this.selection =
      new NaryTournamentSelection<>(
          tournamentSize,
          variation.matingPoolSize(),
          new MultiComparator<>(
              Arrays.asList(
                  Comparator.comparing(ranking::getRank),
                  Comparator.comparing(densityEstimator::value).reversed())));

  this.termination = new TerminationByEvaluations(25000);

  this.evaluation = new SequentialEvaluation<>(problem);
}
We provide many examples of using this class to configure NSGA-II (included the org.uma.jmetal.component.examples.multiobjective.nsgaii package). Some of them are:
NSGAIIDefaultConfigurationExample: NSGA-II configured with default settings to solve a continuous problem.NSGAIISteadyStateExample: The same as the former example, but configuring a steady-state version of the NSGA-IIParallelNSGAIIExample: NSGA-II with a multi-threaded evaluatorNSGAIIStoppingByHypervolume: NSGA-II using a terminator to stop the computation when the hypervolume of the current population achieves a particular value.
Other algorithms are provided with their corresponding builders, such as MOEADBuilder, MOEADDEBuilder, SMSEMOABuilder, RVEABuilder, RVEAStarBuilder, IRVEABuilder, or PAESBuilder. In the case of the MOEA/D builders, constrained problems can be solved by setting a constraint handling subproblem update criterion (see Constraint handling); examples are included in the org.uma.jmetal.component.examples.multiobjective.moead package (e.g., MOEADWithFeasibilityRulesExample, MOEADDEWithImprovedEpsilonExample, MOEADSolvingCF4Example, and MOEADDESolvingCF10Example). RVEAStarBuilder and IRVEABuilder configure the RVEA* and iRVEA variants (reference-vector regeneration, and adaptive vectors with regional protection and an epsilon archive, respectively); see RVEA, RVEA*, and iRVEA for details. PAESBuilder configures a (1+1) evolution strategy (mutation-only variation with a bounded density archive that is both the result and the tiebreaker); examples are included in the org.uma.jmetal.component.examples.multiobjective.paes package (PAESExample with an adaptive-grid archive, and PAESWithCrowdingDistanceArchiveExample with a crowding-distance archive).
The ParticleSwarmOptimizationAlgorithm template
Following the same methodology for designing a component-based template for evolutionary computation, we have designed and implemented a ParticleSwarmOptimizationAlgorithm class. This template was used in the paper “Automatic Design of Multi-Objective Particle Swarm Optimizers”, accepted in the ANTs 2022 conference.
Its run() method is included in this code snippet:
public void run() {
  initTime = System.currentTimeMillis();

  swarm = createInitialSwarm.create();
  swarm = evaluation.evaluate(swarm);
  speed = velocityInitialization.initialize(swarm);
  localBest = localBestInitialization.initialize(swarm);
  globalBest = globalBestInitialization.initialize(swarm, globalBest);

  initProgress();
  while (!termination.isMet(attributes)) {
    speed = velocityUpdate.update(swarm, speed, localBest, globalBest, globalBestSelection,
        inertiaWeightComputingStrategy);
    swarm = positionUpdate.update(swarm, speed);
    swarm = perturbation.perturb(swarm);
    swarm = evaluation.evaluate(swarm);
    globalBest = globalBestUpdate.update(swarm, globalBest);
    localBest = localBestUpdate.update(swarm, localBest);
    updateProgress();
  }
We can observe the specific steps of a generic PSO algorithm, and the use of common components used
also in the EvolutionaryAlgorithm class, such as evaluation and termination.
In its current state, this class is intended to be used in the context of multi-objective optimization,
so it assumes that an external archvive is used to store the leaders found during
the search.
The Component catalogue
The key of having a component-based architecture is to provide a catalogue of components to allow to generate a number of different algorithms by selecting and combining particular components in some way. The following table shows the current components included in the common and ea packages:
Package |
Component type |
Implementations |
|---|---|---|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
Each component type is included in a package containing an interface with the component name and an impl
sub-package where all the implementations of the interface are stored.
Available Components
Selection Components (ea.selection):
NaryTournamentSelection: Best of N random solutions.RandomSelection: Uniform random selection.TruncationSelection: Deterministic selection of top-ranked solutions.RankingSelection: Linear ranking-based roulette wheel selection.StochasticUniversalSampling: Lower variance than standard roulette wheel.BoltzmannSelection: Temperature-controlled selection pressure (control parameter:temperature).PopulationAndNeighborhoodSelection: MOEA/D style mating selection from the neighborhood of a subproblem or from the whole population.PAESSelection: PAES mating selection; returns the current solution or, with a configurablearchiveSelectionProbability, a random member of the bounded archive.
Variation Components (ea.variation):
CrossoverAndMutationVariation: applies a crossover operator followed by a mutation operator.DifferentialEvolutionCrossoverVariation: differential evolution variation.MutationOnlyVariation: applies only mutation (no crossover); used by PAES.
Replacement Components (ea.replacement):
RankingAndDensityEstimatorReplacement: NSGA-II style replacement using ranking and crowding distance.MuPlusLambdaReplacement: (μ+λ) replacement strategy.MuCommaLambdaReplacement: (μ,λ) replacement strategy.RandomReplacement: Zero selection pressure baseline (random replacement).TournamentReplacement: Configurable pressure via tournament size.MOEADReplacement: MOEA/D subproblem update based on an aggregation function (see Aggregation functions); the update rule is delegated to aSubproblemUpdateCriterioncomponent.NSGAIIIReplacement: NSGA-III replacement: it keeps the complete fronts that fit and fills the population from the last one with the niching procedure of the reference points. The objectives are translated by the ideal point and scaled by the intercepts of the hyperplane through the extreme points (the largest translated value of each objective in the first front if the hyperplane is not valid), as in the paper, so the selection does not depend on the position or the scale of the objectives (the scaling is not exact if the scales of the objectives differ by a factor of one million or more, because of the weight of the extreme point search).SMSEMOAReplacement: steady-state SMS-EMOA replacement: it removes the solution of the last front that contributes the least to the hypervolume. The reference point is 1.1 times the maximum value of each objective (the maximum divided by 1.1 if it is negative), so it works with objectives of any sign and range. With constraints it ranks the whole population, so it needs a constraint-aware ranking (see Constraint handling).PAESReplacement: PAES three-way rule for a (1+1) strategy; accepts the offspring if it dominates the current solution, rejects it if dominated, or breaks ties using the bounded archive’s density estimator.ConstraintHandlingReplacement: decorator of another replacement that updates a constraint-handling technique with the population, the offspring and the progress of the run before replacing, once per generation (see Constraint handling).
Subproblem Update Criterion Components (ea.replacement.subproblemupdate): rule used by MOEADReplacement to decide whether a new solution replaces the current solution of a subproblem, enabling constraint handling in MOEA/D (see Constraint handling):
AggregationCriterion: default unconstrained criterion (better aggregation value wins).FeasibilityRulesCriterion: feasibility rules of the constrained dominance principle (Deb, 2000).ViolationThresholdCriterion: adaptive violation threshold (Jan and Khanum, 2013).ImprovedEpsilonCriterion: improved epsilon constraint handling (Fan et al., 2019).ConstraintHandlingCriterion: a pairwise constraint-handling technique, which compares the aggregation function values when the constraints do not decide (see Constraint handling).
Evaluation Components (common.evaluation):
SequentialEvaluation: evaluates the solutions one at a time.MultiThreadedEvaluation: parallel evaluation using threads.SequentialEvaluationWithArchive/MultiThreadedEvaluationWithArchive: variants that additionally store every evaluated solution in an external archive, allowing the result of an algorithm to be taken from the archive instead of from the population.
All of them reject a solution evaluated to NaN with an InvalidConditionException that names the problem (see Problems).
Solutions Creation Components (common.solutionscreation):
RandomSolutionsCreation: Standard random initialization.LatinHypercubeSamplingSolutionsCreation: Stratified sampling for better coverage.ScatterSearchSolutionsCreation: Diverse initial population.OppositionBasedSolutionsCreation: Creates pairs (original + opposite mirrored across bounds center). Reference: Tizhoosh (2005) DOI:10.1109/CIMCA.2005.1631345SobolSolutionsCreation: Creates quasi-random solutions using Sobol sequences for uniform space coverage. Reference: Sobol (1967) DOI:10.1016/0041-5553(67)90144-9CauchySolutionsCreation: Creates solutions using a heavy-tailed Cauchy distribution to balance local and distant exploration. Reference: Yao et al. (1999) DOI:10.1109/4235.771163
Termination Components (common.termination):
TerminationByEvaluations: Stop after a maximum number of evaluations.TerminationByComputingTime: Stop after a given computing time.TerminationByKeyboard: Stop when the user hits return in the console.TerminationByUserRequest: Stop whenrequestStop()is called from another thread, such as the one of a graphical interface or of a web application.TerminationByQualityIndicator: Stop when quality indicator exceeds threshold.TerminationByMutualDominationRate: Adaptive stopping criterion MGBM; stop when the population no longer improves (see Adaptive stopping: the mutual domination rate (MGBM)).TerminationByAnyOf: Stop when any of several termination conditions is met.
For example, the Termination
interface for termination components is as follows:
package org.uma.jmetal.component.catalogue.common.termination;

import java.util.Map;
import java.util.OptionalDouble;

/**
 * This interface represents classes that check the termination condition of an algorithm.
 *
 * @author Antonio J. Nebro
 */
@FunctionalInterface
public interface Termination {
  boolean isMet(Map<String, Object> algorithmStatusData) ;

  default OptionalDouble progress(Map<String, Object> algorithmStatusData) {
    return OptionalDouble.empty();
  }
}
This interface has a method called isMet() that returns true whenever the implemented stopping condition is met.
The default method progress() gives the fraction of the run that has been done, if the condition knows it.
For example, the TerminationByEvaluations class defines that method as shown here:
package org.uma.jmetal.component.catalogue.common.termination.impl;

/**
 * Class that allows to check the termination condition based on a maximum number of indicated
 * evaluations.
 *
 *  @author Antonio J. Nebro
 */
public class TerminationByEvaluations implements Termination {
  private final int maximumNumberOfEvaluations ;

  public TerminationByEvaluations(int maximumNumberOfEvaluations) {
    this.maximumNumberOfEvaluations = maximumNumberOfEvaluations ;
  }

  @Override
  public boolean isMet(Map<String, Object> algorithmStatusData) {
    int currentNumberOfEvaluations = (int) algorithmStatusData.get("EVALUATIONS") ;

    return (currentNumberOfEvaluations >= maximumNumberOfEvaluations) ;
  }
}
The point is that this class has access to the attribute field of the algorithms using it,
so it has access to the current number of evaluations.
Other implementations of Termination allow to stop when a given computing time has been expired,
when a keyboard key is pressed, when the user asks for it, or when the quality indicator value of the current
population exceeds a given threshold.
The algorithms check the termination condition once per iteration, so TerminationByUserRequest lets an
application stop an algorithm that runs in a background thread: the user interface calls requestStop()
(e.g., when a button is pressed), and the algorithm ends at the end of the current iteration and returns its
population at that point. It does not depend on any user interface technology. Combined with
TerminationByAnyOf, the run also ends when a budget is reached, whichever comes first:
var userStop = new TerminationByUserRequest();
Termination termination =
    new TerminationByAnyOf(userStop, new TerminationByComputingTime(maximumComputingTimeInMilliseconds));

EvolutionaryAlgorithm<DoubleSolution> algorithm =
    new NSGAIIBuilder<>(problem, populationSize, offspringPopulationSize, crossover, mutation)
        .setTermination(termination)
        .build();

CompletableFuture.runAsync(algorithm::run).thenRun(() -> showResults(algorithm.result()));

// In the user interface, e.g., when the user presses a "Stop" button
userStop.requestStop();
A request cannot be undone, so a new TerminationByUserRequest is needed for each run.
Adaptive stopping: the mutual domination rate (MGBM)
TerminationByMutualDominationRate implements MGBM (Martí, García, Berlanga and Molina,
Information Sciences 367-368, 2016), one of the stopping criteria compared by Kitamura and Tanabe in
“Benchmarking Stopping Criteria for Evolutionary Multi-objective Optimization” (GECCO 2026). It
decides by itself when to stop, without a budget fixed in advance:
Each time it is checked, it computes the mutual domination rate (MDR) between the current population and the previous one: the fraction of the previous population dominated by the current one minus the fraction of the current population dominated by the previous one. It is 1 when the new population dominates the whole previous one, 0 when neither improves the other, and negative when the population gets worse.
The MDR values are noisy, so they are the observations of a one-dimensional Kalman filter.
The search stops when the estimate of the filter falls below a threshold.
It only uses dominance, so it does not need the ideal or nadir points, and it does not depend on the scale of the objectives. Its parameters are:
Parameter |
Default |
Meaning |
|---|---|---|
|
(required) |
The search stops when the estimate of the MDR falls below it; in (0, 1). |
|
0.05 |
Variance of the noise of the MDR values, and initial covariance of the filter. |
|
0 |
Variance of the change of the MDR between two checks. With 0 the estimate is the mean of an initial value of 1 and all the MDR values so far; a positive value gives more weight to the recent values. |
|
0 |
A solution is dominated only if the other one improves it by more than |
The defaults follow the implementation of Kitamura and Tanabe. Two facts matter when setting the parameters:
With NSGA-II, the MDR does not tend to zero when the search stagnates: on a front that has converged, each population still dominates around 10% of the previous one by tiny improvements, which count as much as large ones. With
epsilon = 0, a threshold below that level never stops the search (withthreshold = 0.12, the value used by Kitamura and Tanabe, NSGA-II did not stop on ZDT1), and a threshold above it stops at a rather arbitrary point. A smallepsilon, such as 0.01, does not count those tiny improvements, so the MDR does fall to zero.A high threshold or a positive process noise stops earlier, also on the plateaus of local fronts: in our runs they stopped NSGA-II on local fronts of DTLZ1 and DTLZ3, with a hypervolume of zero.
In a small study with NSGA-II (population of 100, 100,000 evaluations at most, 10 runs per
problem), threshold = 0.05, processNoise = 0 and epsilon = 0.01 gave these results, where
the hypervolume is relative to the best one of the whole run:
Problem |
Median evaluations at the stop |
Median hypervolume |
Worst hypervolume |
|---|---|---|---|
ZDT1 |
70,200 |
99.9% |
99.8% |
DTLZ1 (2 objectives) |
44,000 |
99.8% |
99.4% |
DTLZ2 (2 objectives) |
20,950 |
99.7% |
99.6% |
DTLZ3 (2 objectives) |
89,300 |
99.7% |
99.6% |
DTLZ1 (3 objectives) |
58,900 |
98.3% |
97.3% |
DTLZ2 (3 objectives) |
26,950 |
95.0% |
93.6% |
DTLZ3 (3 objectives) |
Did not stop in 9 runs |
100% |
96.7% |
The criterion gives more time to the harder problems (DTLZ3) and stops earlier on the easier ones, but it loses more quality with three objectives. These values are a starting point and not tuned defaults: other algorithms, numbers of objectives or population sizes may need other ones. The criterion keeps the state of the run, so a new instance is needed for each run.
As a stopping condition. Combine it with a budget, so that the run ends even if the criterion
never stops it (see NSGAIIStoppingByMutualDominationRateExample):
var mutualDominationRate = new TerminationByMutualDominationRate(0.05, 0.05, 0.0, 0.01);
Termination termination =
    new TerminationByAnyOf(mutualDominationRate, new TerminationByEvaluations(100000));

EvolutionaryAlgorithm<DoubleSolution> nsgaii =
    new NSGAIIBuilder<>(problem, populationSize, offspringPopulationSize, crossover, mutation)
        .setTermination(termination)
        .build();
nsgaii.run();

// mutualDominationRate.estimate() and lastMutualDominationRate() give the state of the criterion
As a warning of stagnation. When the user watches the evolution of the search and decides when
to stop it (e.g., with TerminationByUserRequest), the criterion can just tell the user that the
search seems to have stagnated. An observer passes it the status data of each iteration, and the
criterion never stops the run (see NSGAIIWithStagnationWarningExample):
class StagnationWarning implements Observer<Map<String, Object>> {
  private final TerminationByMutualDominationRate stagnationDetector =
      new TerminationByMutualDominationRate(0.05, 0.05, 0.0, 0.01);
  private boolean warned = false;

  @Override
  public void update(Observable<Map<String, Object>> observable, Map<String, Object> data) {
    if (stagnationDetector.isMet(data) && !warned) {
      warned = true;
      // Tell the user, e.g., with a message in the user interface
    }
  }
}

algorithm.observable().register(new StagnationWarning());
The algorithms of jmetal-component check the termination condition, and notify the observers,
once per iteration. In a steady-state algorithm, such as SMS-EMOA, an iteration produces a single
solution, so two consecutive populations differ in one solution at most and the MDR behaves
differently; the values above are not valid for them.